
- Anyone can buy the same baseline intelligence from AI. What competitors can't copy is the data that comes out of your real operations.
- The most valuable data rarely sits in a tidy database. It is in job sheets, emails and scattered files.
- Start by taking stock of what is where and who owns it, before you think about technology.
1. When baseline intelligence can be bought, specific knowledge gains value
If you and your competitors use the same AI, you get the same intelligence. The one thing they can't copy is what happens only inside your company: what customers have complained about, which jobs have gone wrong and how your technicians fixed them. That is something money can't buy.
General-purpose models keep getting better at writing, summarizing and analyzing, but they don't know how your company defines a quality customer, which conditions make projects run late or which kinds of answers keep customers loyal. This information comes from real work and isn't on the internet.
A data moat means having data that is linked to outcomes, is of good quality, can be used with the right permissions and is fed back into decisions. Sheer volume has little to do with it. Competitors may copy an AI feature within a few months, but they will find it hard to copy a history of feedback and specific understanding built up over years.
2. Five types of data that set you apart
Data varies widely in value. Information anyone can find on the internet hardly helps, while a record of how each kind of case played out inside your company is rare.
- Behavioral Data: What customers actually do, as opposed to what they say they like.
- Outcome Data: Which solutions led to sales, repeat use, better quality or savings.
- Exception Data: Which cases fell outside the standard, and how experts resolved them.
- Domain Knowledge: The rules, reasons and trade-offs that people in the industry know.
- Feedback Data: Edits to drafts, rejections, and the reasons an output didn't fit.
A large pile of marketing documents may be worth less than a history of sales objections linked to their outcomes. Data becomes valuable when it helps answer decision questions and improve the workflow. Size alone doesn't make it valuable.
3. Take a data inventory the way a business owner would
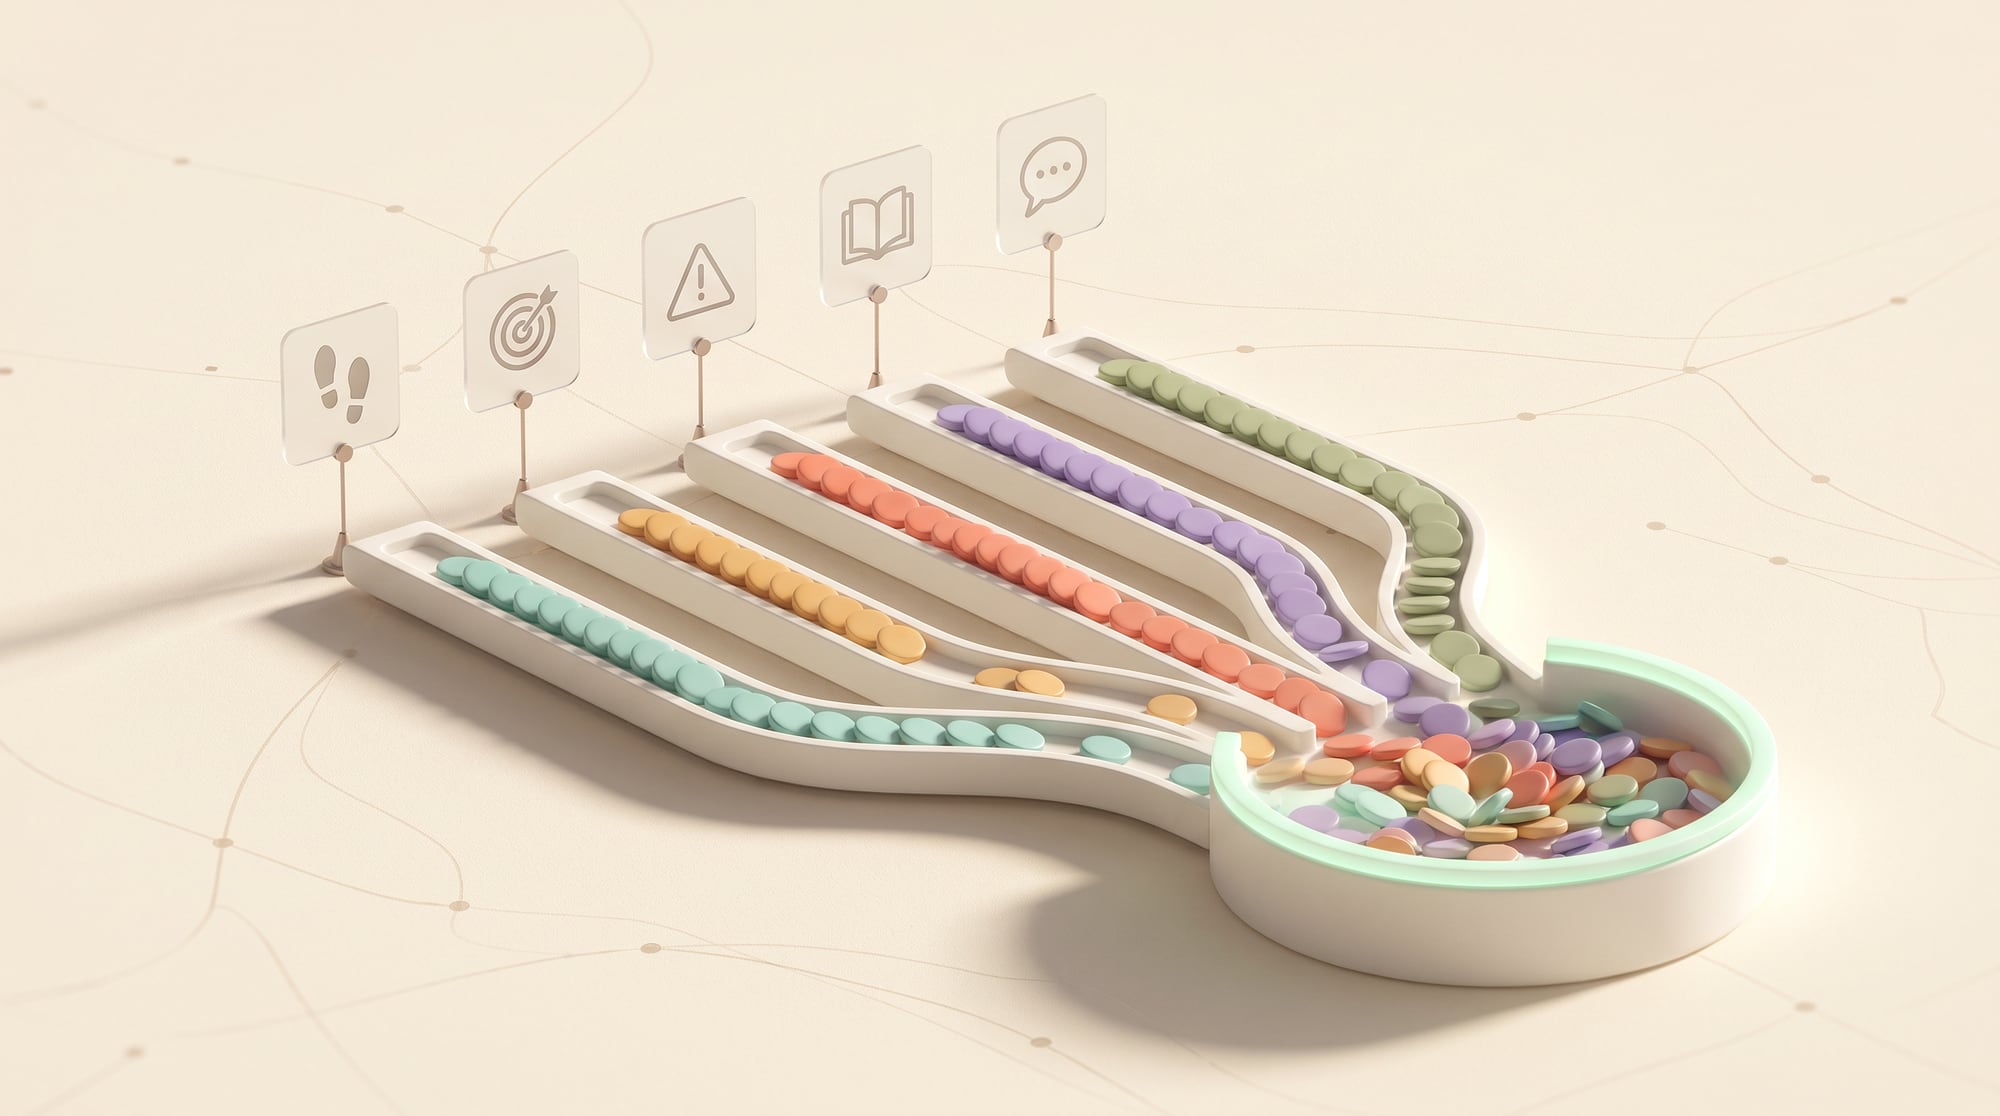
Start from a use case instead of surveying every database. Pick an important decision, such as prioritizing leads or recommending substitute products, then identify the data it uses, along with its source, owner, quality, permissions and the outcome it links to. Map the data lineage: where each number or answer comes from and when it is updated.
| Data | Owner | Quality | Permission to use with AI | Linked outcome |
|---|---|---|---|---|
| Customer history | Sales Ops | Key fields 85% complete | Internal only | Conversion/Retention |
| Tickets | Support | Good text, inconsistent categories | PII must be masked | Resolution/CSAT |
| Manuals | Product | Some sections out of date | Usable by group | Answer Quality |
Assign tiers: Critical, Useful and Archive. Don't try to clean everything at once. Invest in the data the first workflow needs and build standards that can scale. Data with no owner shouldn't be used as ground truth.
4. Turn scattered files into a knowledge layer
For the development team · System architecture
A knowledge layer needs approved content, metadata, versions, effective dates, owners and an access policy. If you load every file into a vector database without tracking its status, AI may pick up old prices and policies that have been withdrawn. Define an order of precedence between sources and how the system should answer when data conflicts.
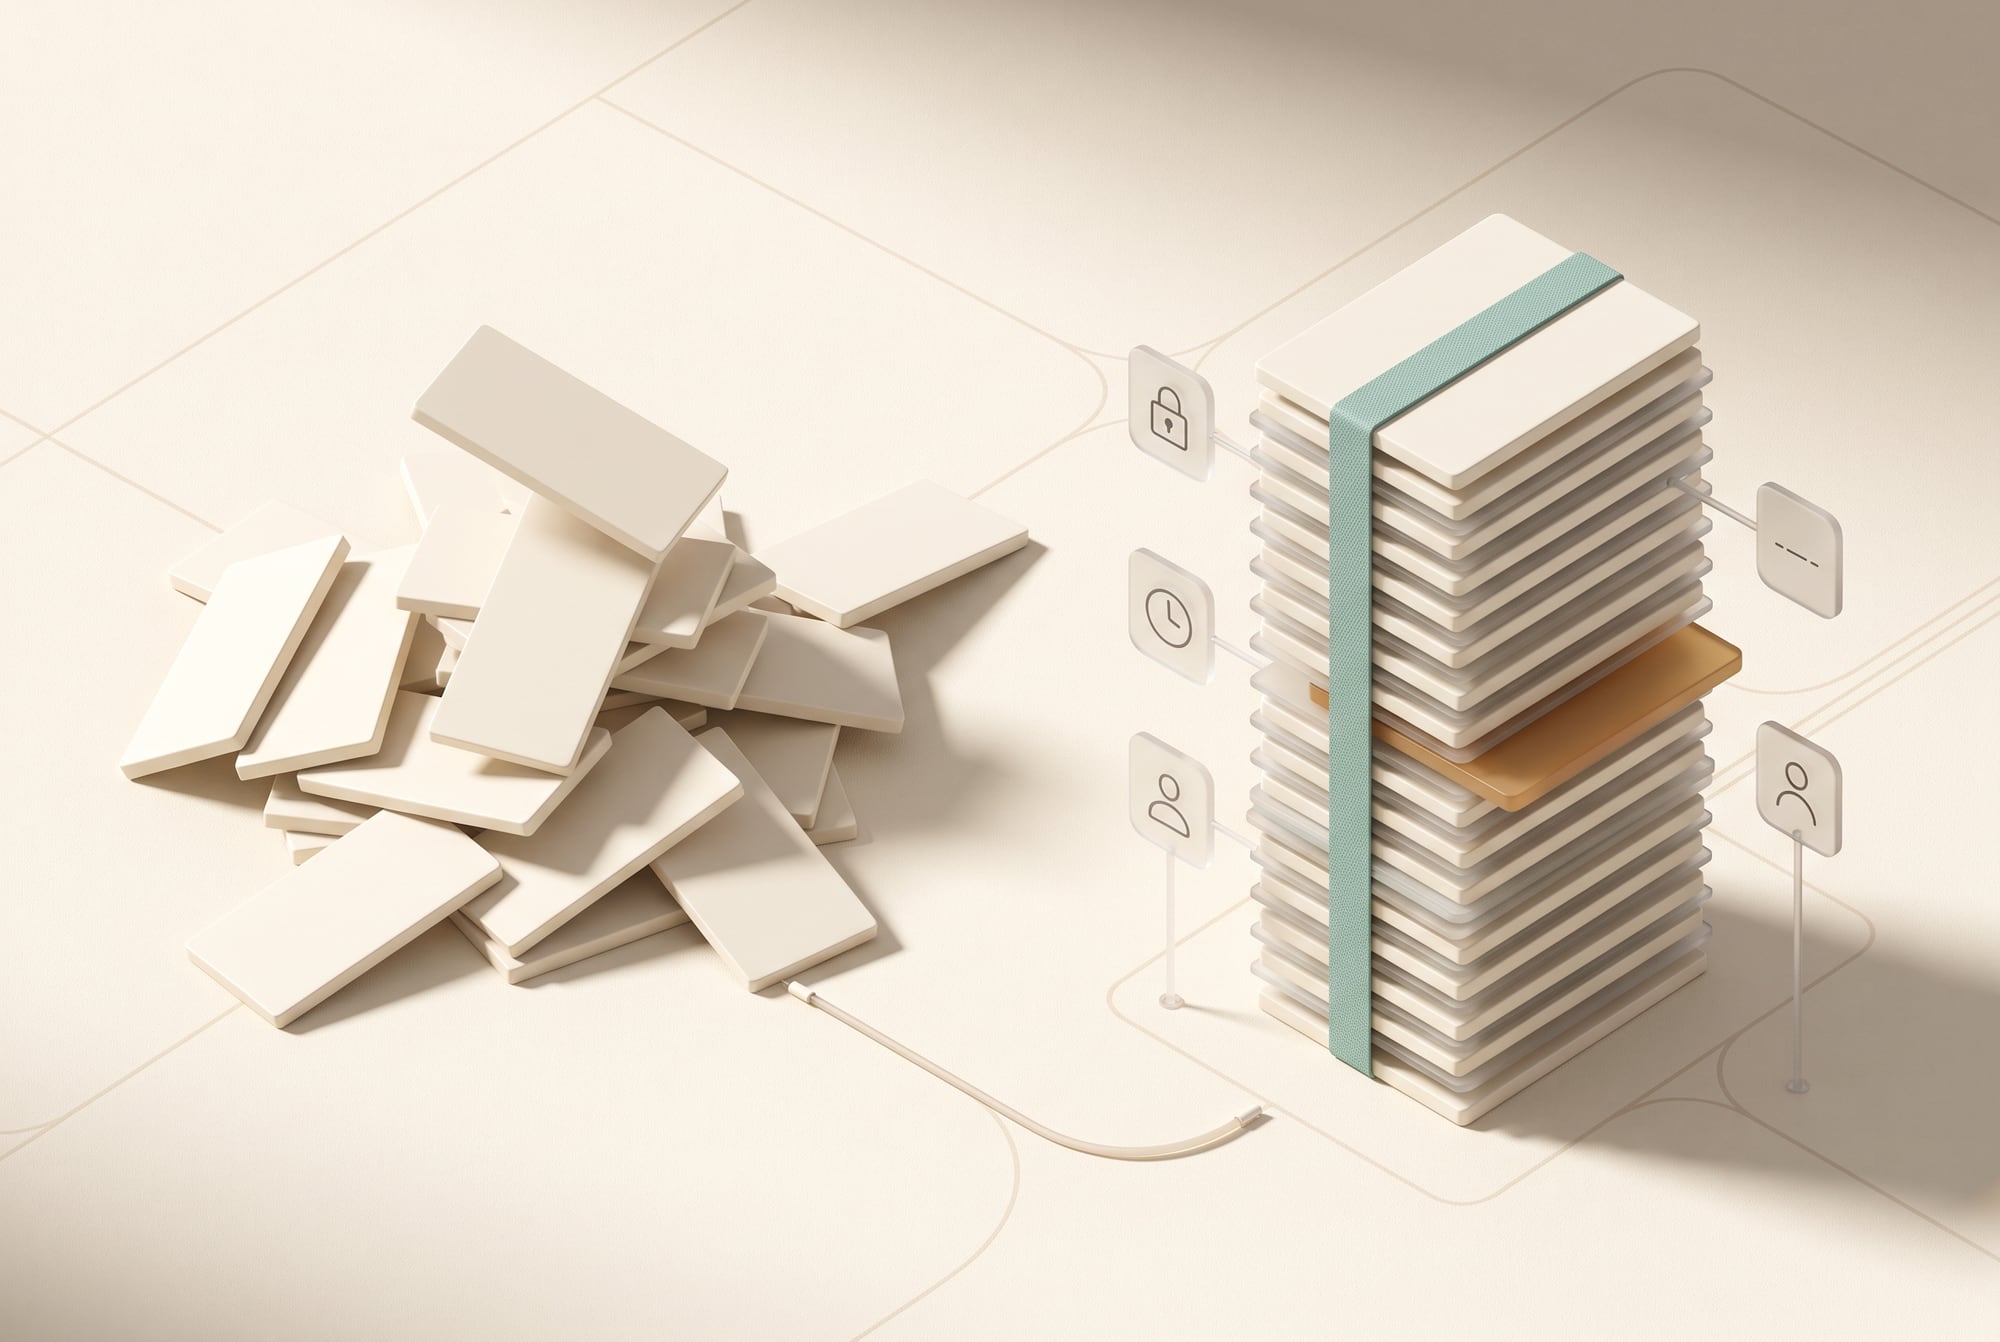
Separate facts, policies, examples and opinions. Facts must come from core systems. Policies need an approver. Examples teach a pattern but are not rules. Opinions should be labeled as opinions. The system must cite its sources and show dates so users can check them.
For the development team · Technical detail
Set up a content lifecycle: Draft → Review → Approved → Deprecated, with reminders to owners. Maintaining knowledge is ongoing operational work. It can't be treated as a one-off migration project.
5. Build a feedback flywheel that improves with every transaction
When people correct an AI output, don't keep only the final version. Record what was changed, the type of error and the reason, and link it to the segment and the outcome, such as an edited message that closed a sale or an answer that cut repeat tickets. This data is used to refine prompts, rules, knowledge and evaluation.
Feedback shouldn't all be fed into training automatically, because people may make the wrong correction or the case may be a special one. Golden data needs sampling and approval. Choose feedback that is high quality and varied, to reduce bias from any single group of users.
6. Permissions, quality and trust are part of the moat
For the development team · Technical detail
Data you can't use, because there is no consent or because it is at risk of leaking, isn't an asset. Define purpose limitation, retention, masking and role-based access. Keep data for operations, analytics and model improvement separate, and don't assume that one permission covers every purpose.
Create a data quality SLA for key fields, covering completeness, freshness and accuracy, with someone responsible when they are wrong. Monitoring must catch drift, for example when customer patterns change but the rules stay the same, and customers need a way to correct their own data in line with the relevant requirements.
For the development team · Technical detail
Make sure you have export and portability, and don't tie your knowledge to a single vendor. Keep sources, metadata and evaluations in portable formats so the data moat stays with the company instead of being locked inside a service you can't leave.
7. Turn data into business results, and avoid data projects that lead nowhere
- Cut costs: Good knowledge brings a high auto-resolution rate and less review.
- Grow revenue: Behavioral plus outcome data helps recommend the right offers and timing.
- Create products: Exception patterns reveal problems nobody has solved yet.
- Raise switching costs: Results improve with each customer's own data, with transparency and permission.
- Reduce risk: Lineage and evidence support audits and explain decisions.
For the development team · Technical metrics
Every data initiative should have a value hypothesis and a metric, such as cutting search time by 40 percent, raising first-contact resolution by 15 points or building a lead score that increases conversion. Don't use the number of files imported or the size of the database as a stand-in for value.
8. An 18-month roadmap for building a data moat
For the development team · System architecture
Months 1 to 3: Choose the use case, inventory the key data, appoint owners and measure quality. Months 4 to 6: Build the knowledge layer with lineage and test the first workflow. Months 7 to 12: Link feedback to outcomes and build a golden dataset and evaluations. Months 13 to 18: Expand across products, build reusable data products and assess opportunities for new offerings.
In short: A data moat comes from specific data that is linked to outcomes and has owners, permissions and a feedback loop. Piling up files doesn't create one. Companies should start with their important decisions, build a knowledge layer and capture corrections in a structured way. When models change, the company's knowledge and its learning system will keep setting it apart.
Turn scattered files into an asset your systems can use
A company's most valuable data rarely sits in a tidy database. It is in the job sheets technicians fill in by hand, the emails the sales team sends to customers and the files managers keep for themselves. Your team owns this knowledge. DNA Maker's role is to help with a data inventory that shows what is where, who owns it, which datasets can genuinely support which decisions, and which are still too poor in quality to use. This step often reveals that the company has more good material than it thought, but in forms that machines can't read yet.
The work we do together with your team
Next, we design storage with clear metadata and access rights, build data pipelines so new data flows in consistently, and create a RAG search layer that answers questions with references to its sources, so employees can trust the answers and check them. What turns data into a real advantage is the feedback loop: every time someone corrects an answer or closes a job, the system must capture that and feed it back into the store. If you have a document library so hard to search that employees would rather phone each other to ask, that is a starting point we can help with.
SOFTWARE ENGINEERING GLOSSARY
Software engineering glossary
These terms are useful when you talk about turning internal data into something your systems can use.
| Term | What it is | A simple example | What executives should ask the development team |
|---|---|---|---|
| Metadata | Data that describes data, such as who created it, when, and which product it applies to, so it can be searched and filtered | Recording which machine model a manual covers and when it was last updated | Without metadata, how will the system know which documents are still valid? |
| RAG | A method that lets AI look up the company's real data to build its answer, instead of guessing from general knowledge | You ask how to set up a machine, and the system answers from the latest manual | Which version of which document does an answer cite, and what does the system say when it can't find the information? |
| Citation | Referencing the source of an answer so it can be checked | The answer includes a link to the manual page it used | If users don't believe an answer, how can they check it further? |
| Data Pipeline | The route data takes from its source to where the system uses it, with cleaning along the way | Pulling the day's job sheets into the knowledge store every night | If the source data changes format, will the system notice and send an alert? |
| Data Retention | The policy on how long data is kept and when it is deleted | Keeping customer conversations for the period set by law and company policy | What do we keep, for how long, and who approved this policy? |