
- Outages come in three kinds: the system can't handle the traffic, data gets lost, or something breaks quietly without anyone knowing. Each one needs different preparation.
- A backup you have never tried restoring doesn't count as a backup yet.
- Business owners have to answer two questions themselves: how long can the system be down, and how many hours of data can you afford to lose? The technical team designs around those answers.
Three kinds of outage businesses run into
It is 8 p.m. sharp on campaign day, and thousands of customers hit the website at once. Pages start spinning, the marketing team asks in the group chat what is going on, and nobody can answer. This is the kind of outage people picture first, but the kind that does more damage is usually quieter.
The first kind is being unable to handle the load. A system that copes easily with normal traffic slows down until it is unusable when more people arrive at once than it has ever seen. The bottleneck is usually the database, and adding more web servers won't help.
The second kind is data loss. The causes range from a staff member deleting the wrong table and hardware failure to ransomware that encrypts every file. That last one will spread to the backups as well if they are permanently connected to the main system.
The third kind is a silent failure. The website still opens, but some key steps have stopped working. Customers pay successfully but the order isn't recorded, or the confirmation email never goes out. This is the most expensive kind, because hours pass before anyone notices, and every transaction then has to be fixed one at a time.
Apps built with vibe code come with every screen in place, but no monitoring, no data backups and nobody who gets woken up at 2 a.m. Nobody told the AI to build those things, and during the demo nobody saw they were missing.
Four layers of readiness, and the evidence to ask for
A restaurant that is ready for Friday night knows how many dishes the kitchen can turn out per hour, has someone watching the front of house, has a backup stove for when the gas runs out, and everyone knows who makes the call when the power goes. An online system needs the same four things, and each one comes with evidence a business owner can ask to see without understanding the technology.
| Readiness layer | The business owner's question | Evidence to ask for |
|---|---|---|
| Capacity | How many users can the system handle at the same time before it slows down? | The latest load test results, with the figures and the test date |
| Visibility | If something went wrong right now, who would know first, our customers or us? | The monitoring dashboard and the list of alerts that have been set up |
| Recovery | If the database were lost now, up to what point could we get the data back, and how many hours would it take? | The record of the most recent data recovery drill |
| Response | If the system goes down on a Saturday night, who decides, and who tells customers? | A runbook and an on-call roster with real names on it |
The recovery layer needs two answers from the business owner. The first is how long the system can be down before the damage to the business becomes unacceptable. Engineers call this the RTO. The second is how far back you can afford to lose data, called the RPO. A shop taking dozens of orders a minute can't accept an RPO of one day, because that would mean losing a whole day of orders, while a company website updated once a month can live with it easily. The shorter you set these two values, the higher the cost, so the numbers should come from the business.
The long-standing rule for backups is 3-2-1: keep three copies, on two types of media, with one copy off-site. The off-site copy that isn't connected to the main system is the one that survives a ransomware attack.
For the development team · Technical detail
Set SLOs for the order and payment path. Alert on the symptoms customers experience, such as error rate, P95 latency and payment success rate. Run synthetic checks that simulate an order every few minutes. Use point-in-time backups with automated restore tests, load test at levels above the expected peak, and take orders through a queue so that transactions aren't lost when the database slows down.
Hypothetical case
A cosmetics brand and the first twenty-five minutes of its campaign
A cosmetics brand that sells through its own website launches a campaign at 8 p.m. At 8:04 the site starts to slow. At 8:10 the checkout page freezes. Some customers are charged but never get an order number, because the bank's confirmation signal arrives while the system isn't responding. The team finds out from comments on the brand's page at 8:25 and manages to restart the server at 8:40. The next morning, three staff have to match the bank's charges against the orders in the system one by one.
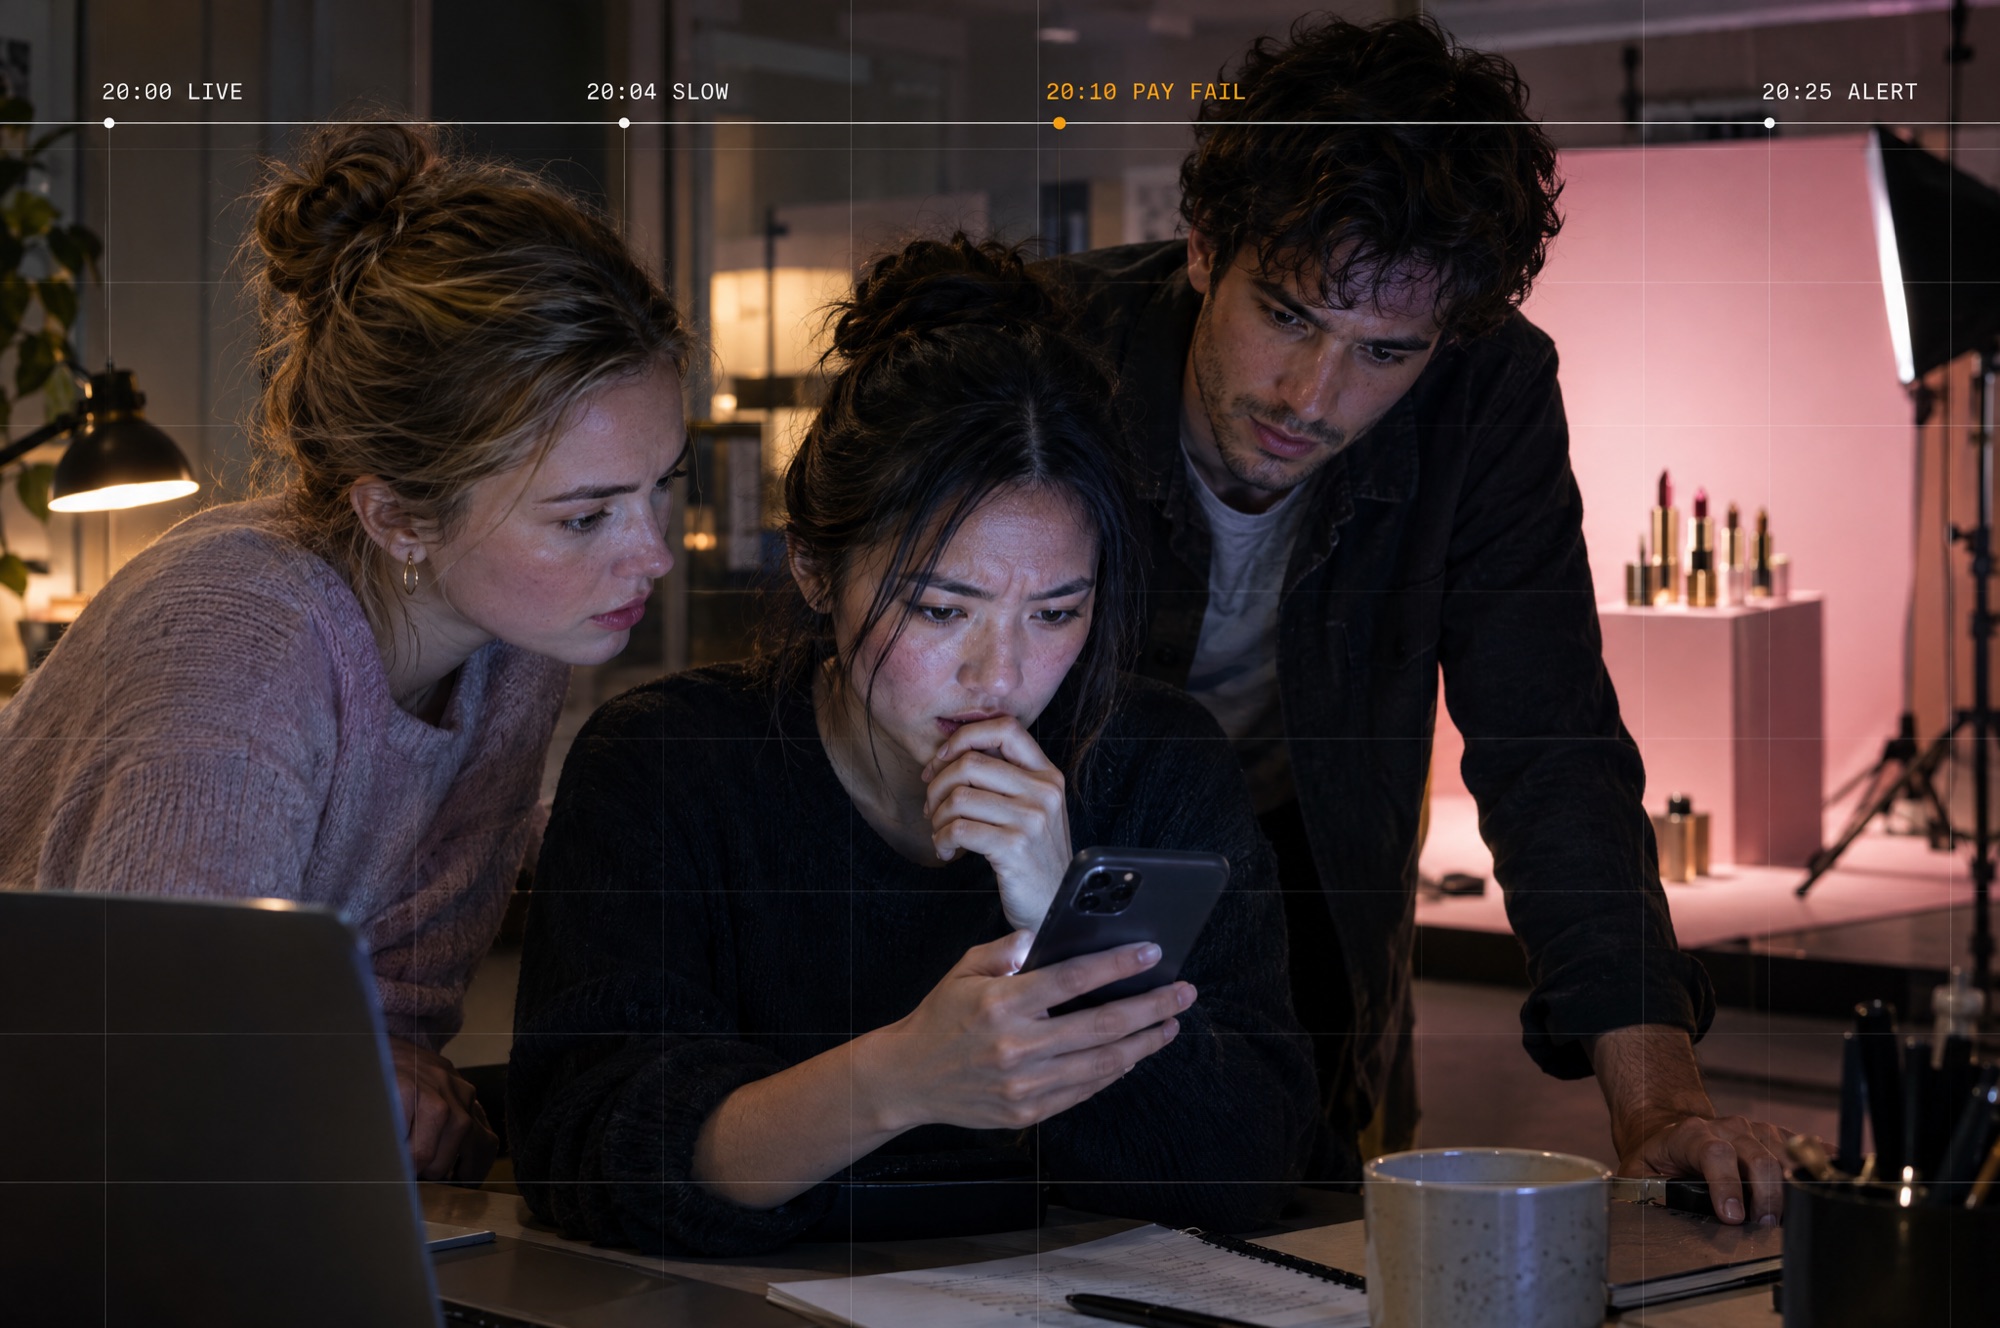
Look back at what each layer of readiness would have changed. A load test a week before the campaign would have shown that the database was the bottleneck. Alerts tied to the payment success rate would have told the team within two minutes. An order queue would have held the bank's signals until the system came back. And a runbook would have said who posts the announcement on the page, so nobody had to ask in the middle of the incident.
Run a recovery drill every quarter
- Pick the latest backup of the main database.
- Restore it onto a separate machine, away from the live system, and time it from the start until it is usable.
- Check three things: what time the latest order in the backup is from, whether the number of customers matches the live system, and whether you can log in and open orders.
- Write down the time it took and the window of data that was lost, then compare them with the targets the business owner set.
- Fix whatever got stuck, then schedule the next drill.
The evidence is a drill record with the date, the time taken and the name of the person who ran it. Where drills often come unstuck is that only the database has been backed up, while product images, documents customers uploaded and system settings live somewhere else that has never been backed up.
What level of readiness is worth it for your business
Shops that sell through a marketplace or a ready-made store platform hardly need to think about this, because the provider already takes care of it. This article is about businesses with their own systems, which have to decide for themselves how many layers to prepare.
A workable way to think about it is to estimate the cost of downtime per hour. Take peak-hour sales, add the labor cost of the team that has to clean up, add the customers who won't come back, and compare the total with the cost of each readiness layer. Businesses with low downtime costs should at least have backups that have been through a recovery drill, plus basic alerts, because these two cost little and prevent damage that can't be undone.
A sensible order of investment is to start with backups and recovery drills, then monitor the paths that touch money, then run load tests before big campaigns, write a runbook and rehearse incident response, and finally, for businesses that can never stop, add a standby system that takes over automatically, known as failover.
Move up to the next layer when
- Peak-hour sales are higher than the cost of preparing that layer
- A campaign is expected to bring more visitors than the system has ever handled
- Customers have spotted an incident before the team did
- You have contracts with corporate customers that commit you to service times
The numbers to track after investing are the time from an incident to the team knowing about it, the time from knowing to the system coming back, the number of incidents customers spotted first, and the result of the latest recovery drill. If the time it takes the team to notice an incident doesn't fall after monitoring is installed, the alerts are still tied to machine metrics instead of what customers experience. Fix that before buying more servers.
Get your systems ready before the next big campaign
Your executives decide how much downtime the business can accept, marketing knows the campaign calendar, and customer service knows what customers ask when the system has problems. DNA Maker gathers answers from all three and turns them into targets for the system: the periods when it must not go down, the paths to watch from order through payment to order confirmation, and the chain of decisions when an incident happens.
Our team reviews the architecture, runs load tests and stress tests to find the bottlenecks, sets up monitoring and alerts on the paths that touch money, sets backup schedules with recovery drills, and writes the disaster recovery plan and runbook together with your team. For systems that need high availability, we design the scaling and the standby servers. If you have a big campaign coming up in the next two or three months, bring the campaign calendar and the notes from the last time the system had problems, and the work will start from the riskiest point.
SOFTWARE ENGINEERING GLOSSARY
Software engineering glossary
Use these terms to agree with the technical team how much the system has to withstand. The first two are numbers the business side has to set.
| Term | What it is | A simple example | What executives should ask the development team |
|---|---|---|---|
| RTO | The longest time the system is allowed to be down, from the moment of the incident until it is back in use | A shop decides the checkout page must be back within thirty minutes | Have we ever actually hit our RTO in a drill? |
| RPO | How much data you can accept losing when you have to restore from a backup | Backups run every fifteen minutes, so if a restore is needed, the lost orders go back no further than the last fifteen minutes | If we had to restore now, what time would the latest data we got back be from? |
| Backup | A copy of data stored separately from the main system, used to restore when the real data is damaged or lost | The order database is copied to another location every night, with thirty days of history kept | Where are the backups stored, who can access them, and when did we last try a restore? |
| Load Test | Simulating a large number of users on the system at once, to measure how much it can take and where it gets stuck | Simulating five thousand customers buying at the same moment, a week before the campaign | At how many users does the system start to slow down, and which part is the bottleneck? |
| Runbook | A step-by-step guide for handling incidents you have planned for, naming who acts and who decides | When the checkout page goes down, the guide says who checks what, who posts on the page and what message to use | When was this guide last used in a drill, and have the people on the on-call roster read it? |
| Disaster Recovery | The plans and systems for restoring service after a major incident, such as a data center outage or data being encrypted | When the cloud provider goes down across a whole region, the team brings the system up from a copy in another region | Which incidents does this plan cover, and who has to be involved to set it in motion? |
| Failover | Switching automatically to a standby server or system when the main one stops working | The main database goes down and the system switches to the standby within a minute, with nothing for customers to do | Has the switchover been tested on the real system, and is any data lost during the switch? |