- An enterprise AI system has seven layers. Any layer the company does not decide, the vendor decides for you.
- Cloud or on-premise is a separate answer for each layer, but the layers that hold permissions and logs should stay on your side.
- Start with one job, agree what counts as passing first, then build from the data up.
One AI system has seven layers
Think of opening a new branch. You need a shopfront, a manager, staff, a filing cabinet, a direct line to the warehouse, approval rules and a month-end report. An AI system has the same parts, and for each one you can rent a cloud service or install it inside the company, on-premise.
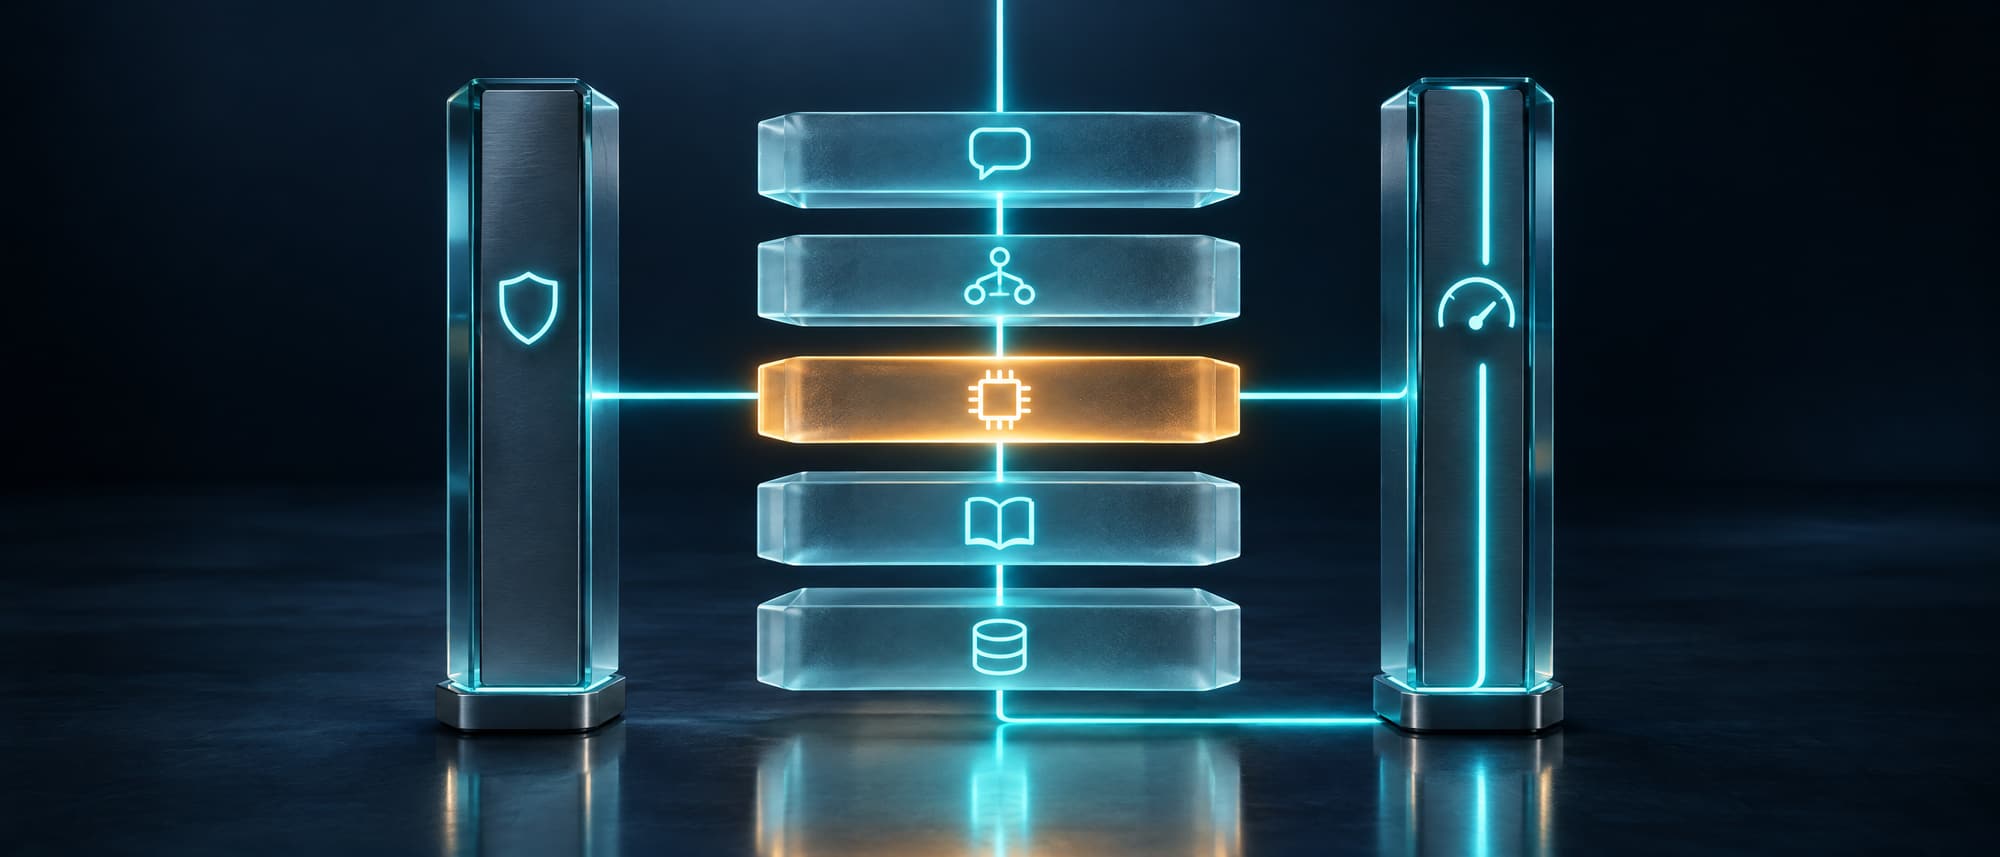
The picture for this chapter is five layers stacked top to bottom: channel, orchestration, model, knowledge, and data and systems. Two pillars touch every layer: control and measurement. A question flows down toward the data, and the answer flows back up, passing the control pillar every time it crosses a layer.
Layer 1, the channel: where people type the question
The channel is LINE, the web, an app or email. IT decides which channel opens first and how the system knows who is typing. A good first channel is the one people already use. The common mistake is a channel that is not tied to staff accounts, so the system cannot tell who should see what. LINE messages always pass through LINE's servers. If the data cannot leave the company, use an internal web page with SSO sign-in and let LINE send notifications only.
Layer 2, orchestration: who decides the next step
Orchestration decides whether to search documents, call a system, ask the model or hand over to a person. A workflow engine follows a written sequence; an agent loop lets the model choose the next step itself. IT decides which jobs get which. A job whose steps are the same every time should be a workflow: easier to check, and cheaper in model calls. The common mistake is an agent for every job with no limit on loops. This layer can run on-premise, for example LangChain on Kubernetes. For a case with many agents, see Multi-agent business platform.
Layer 3, the model: cloud, private or both
On the cloud side are the enterprise plans of Claude, GPT and Gemini: strong, with no machines to look after, but the text leaves the company. On the self-hosted side is a private LLM such as Llama or Qwen on vLLM or Ollama: the data stays in the company, in exchange for looking after the hardware. IT decides which job goes to which model through model routing. Jobs that carry customer data go to the in-house model; general jobs go to the cloud. The common mistake is code tied to one provider's model. Read more in Don't tie your business to a single AI provider and the private AI options.
Layer 4, knowledge: the documents AI answers from
The system searches your documents before it answers, using RAG. Documents are turned into numbers that stand for their meaning, called embeddings, and kept in a vector database. IT decides which version is the real one, who owns it and who may see what. Scanned files need OCR, and written Thai has no spaces between words, so search by meaning should run alongside search by keyword. The common mistake is loading the whole shared drive, old versions mixed with new. The whole layer can run on-premise, for example Elasticsearch with your own embedding model.
Layer 5, data and systems: API, MCP and RPA
AI reaches the ERP, CRM and accounting system in three ways. An API is the door a system opens for other programs to call. MCP wraps an API so the AI can choose to use it. RPA clicks through screens in place of a person, for old systems with no API. IT decides whether the AI only reads or also writes, and where the source of truth for each kind of data lives. The common mistakes are one admin account for the AI into every system, and RPA that stops whenever a screen changes. The connectors should run on the same network as the ERP, even when the model is in the cloud. Read more in connecting an app to your ERP and legacy data.
Layer 6, control: permissions, approvals and logs
This layer sets who can ask what, which tools the AI may call, which jobs need an approval point and what the guardrails check, and it records every step in an audit log. It also blocks prompt injection: text in a document that secretly instructs the AI. IT decides whether the AI's permissions are tied to the person asking. Tied through Active Directory, the system sees no more than that person can see. The common mistake is writing "never reveal salaries" in the prompt and calling it control. Control has to be code outside the model, and it always stays on your side.
Layer 7, measurement: is it right, and what does each job cost
The main tool is a test with real examples from your own work, run before go-live and again every time the model, the documents or the prompt changes. Next to it sits a dashboard showing the answers people had to fix and the cost per job. IT decides before launch who signs off answers and what the pass mark is. The common mistake is starting to measure after go-live. Cloud models charge by the volume of text, while a private LLM is a fixed machine cost, so the per-job figure tells you which jobs should move sides.
How MCP differs from an API
Think of an office building. An API is a numbered door: a programmer writes in advance which doors to open, in which order. MCP is the directory by the lift that says what each room does; the AI reads it and picks the room itself, depending on the question.
According to the official documentation, MCP, the Model Context Protocol, is an open standard for connecting AI applications to outside systems. The AI application is the host, and it creates one client for each server. A server offers tools for taking action, resources for reading, and prompts, which are instruction templates. Each tool has a name, a description and the shape of the data it expects.
The credentials for the target system stay with the MCP server, and the model never sees them. Most MCP servers wrap the ERP's existing API, so you keep the API you have, and every AI application that supports MCP can use the same server. If the steps are fixed, such as sending the day's sales to the accounting system every night, let a workflow call the API directly. If the AI has to choose the system depending on the question, use MCP. Permissions are still layer 6's job.
Build order: from the data up to the screen
Many projects start with the chat screen and get stuck on data and permissions later. The safer order is:
1. Pick one job and, before writing code, agree who signs off the answers and what counts as passing (layer 7). 2. Decide which data may leave the company and which systems the AI may touch (layers 6 and 5). That answer settles which side layers 3 and 4 sit on. 3. Give every document an owner and a current version (layer 4). 4. Choose the models and the routing rules (layer 3). 5. Start with a workflow, then add an agent loop (layer 2). 6. Open the one channel people already use (layer 1).
Hypothetical case
An auto-parts plant in Rayong (name and details invented) wants line supervisors to get work instructions and customer specs the moment they ask. Customer part drawings may not leave the plant under contract, so IT chose a private LLM inside the plant. The channel is an internal web page on each line's tablet, and LINE only flags jobs waiting for approval. The ERP is connected through a read-only MCP server. The only write job is drafting a defect report, which the QC lead must confirm.
The QC team tested the system with real questions from their own work. In the first round the system answered from an old manual mixed into the library, so the team kept only the versions in use, showed the version number in every answer and retested until it passed, before opening it to the first line.
One question per layer
- If a layer has no answer yet, do not move on.
Layer 1: Where do the people who will use the system type their questions today?
Layer 2: Are the steps of this job fixed, or do they depend on the result of the step before?
Layer 3: What is the most confidential data that will pass through the model?
Layer 4: Which version is the real one, and who owns it?
Layer 5: Does the AI only read, or does it write into the system too?
Layer 6: When the AI gets it wrong, who stops it, and how is it reversed?
Layer 7: Who signs off the answers, and what is the pass mark?
| Layer | Decides | Cloud | On-premise | Common mistake |
|---|---|---|---|---|
| 1 Channel | First channel, identity | LINE OA, web chat | Internal web with SSO | Not tied to staff accounts |
| 2 Orchestration | Workflow or agent loop | Cloud workflow | LangChain on Kubernetes | An agent for every job, no loop limit |
| 3 Model | Which job goes to which model | Claude, GPT, Gemini | Llama, Qwen on vLLM | Code tied to one provider's model |
| 4 Knowledge | Real version, owner, who may see | Cloud document search | Elasticsearch in-house | Old versions mixed with new |
| 5 Data and systems | Read or write, where the source of truth is | SaaS connectors | MCP server next to the ERP | One admin account for everything |
| 6 Control | Permissions tied to the asker, approval points | The provider's filters | Active Directory, audit log | A prompt instead of control |
| 7 Measurement | Who signs off answers, pass mark | The provider's reports | Dashboard, in-house testing | Measuring after go-live |
Check these eight before you approve an AI design
- The diagram shows all seven layers, and every layer names a system or provider.
- It marks where personal data leaves the company, under PDPA, Thailand's personal data protection law.
- The AI sees no more than the person asking is allowed to see.
- Write tools are separate from read tools and have an approval point.
- The audit log records the real user, the tool called and the result.
- Testing with real examples, and the pass mark, are agreed before building starts.
- The model can be swapped without rebuilding the other layers.
- Cost per job can be measured from day one.
For the development team · MCP servers vs REST endpoints, identity propagation and least privilege
A REST endpoint is called by code written against its documentation. An MCP server exposes tools over JSON-RPC 2.0: the client calls tools/list to get each name, description and inputSchema, then calls tools/call. Tool descriptions therefore land in the model's context, so review any third-party server before installing it. Identity propagation: the server takes the user's identity from SSO, decides permissions, and calls the downstream API with a token issued to itself; the MCP specification forbids token passthrough. Least privilege: split read and write tools, use no wildcard scopes, and route write tools through an approval policy or elicitation. Run stdio servers in a sandbox and log every tool call with its user.
How we design all seven layers for organizations in Thailand
The people who know which document is the real version and who may approve what are your team. DNA Maker starts by sitting with IT and the process owners and drawing the seven layers on one sheet of paper, marking which level of data passes through which layer and where a person must approve, before anyone picks a model.
The team that works with you is DNA Maker's own, with no subcontracting, and you see a demo every week. When data cannot leave the company, we install a private LLM with Llama or Qwen on vLLM, together with Elasticsearch and Active Directory. When the cloud is allowed, we keep the control layer and the MCP connectors on your side. Approval points and the audit log are there from the first version. Scope and price are fixed before work starts, and source code and documents are handed over per the scope in the contract. This is the kind of work we do for banks, hospitals and large Thai groups. See the Private LLM and AI Workflow pages, or ask Dream on the chat page.
SOFTWARE ENGINEERING GLOSSARY
Software engineering glossary
| Term | What it is | A simple example | What executives should ask the development team |
|---|---|---|---|
| MCP | An open standard that lets AI applications discover and call other systems' tools | An AI assistant decides on its own to check stock in the ERP | Whose permissions does the MCP server use? |
| RPA | Software that clicks through screens in place of a person, for systems with no API | A bot keys invoices into an old accounting program | When the screen changes, who fixes it? |
| Embedding | Numbers that stand for the meaning of a text, used to search by meaning | Ask about "maternity leave" and find the clause on "leave for childbirth" | Where does the embedding model run, and how well does it read Thai? |
| Model routing | Sending each job to the right model by difficulty and confidentiality | Questions containing customer names go to the in-house model | Who can change the routing rules? |