- An AI agent comes with two bills: a build cost you pay once and a running cost you pay every month.
- Three things move the price most: how many systems the agent touches, what one wrong answer costs you, and whether your data may leave the company.
- Start with one channel and one job, and measure before you add more.
- A good quote shows both bills and says who each running cost is paid to.
The price of an AI agent comes as two bills
Think of a coffee shop. The fit-out and the espresso machine are paid for once. Beans and electricity are paid every month, and the busier the shop, the faster the beans run out. An AI agent is costed the same way. The first bill is the build. The second is the running cost, which grows with the number of conversations and the work the agent does.
That is why a quote with a single figure usually describes the first bill, and the second one turns up after launch. How an agent differs from a chatbot is covered in AI agent, agentic AI and generative AI: what is the difference? To weigh the total cost of ownership against the manual work you do today, see How much is manual work costing your business each month?
The build bill: six things set it
The build cost is the development team's time, and six things decide how much of it you need.
Channels come first. LINE OA, Facebook Messenger, a website chat and a mobile app each have their own message format and their own way of identifying the user, so every channel you add brings another round of integration and testing.
Then the knowledge sources. If the answers live in one set of documents that someone maintains, this part is quick. If they are spread across Excel files, scanned PDFs and the memory of senior staff, the team has to gather them and have the owner of each process sign them off before they go into the knowledge base.
The systems the agent connects to are the biggest driver. An agent that only reads order status from your ERP is quicker to build than one that creates orders, because writing data needs permission checks, handling for when the other system is down, and a record of who asked for what.
Approval and handover design tends to go missing when people ask for a price. You need to agree which actions the agent takes on its own, which it only proposes, and when it hands the conversation to a person along with the chat history. That includes the screen your staff use to pick up cases and an audit log.
Language matters more in Thailand than in most markets. Thai customers mix Thai and English and spell by sound, and models understand Thai to very different degrees. You can choose a large model that reads Thai well and costs more per call, or a smaller model that needs more testing. Every extra language, such as Japanese or English for a foreign-owned company, has to be tested again with real examples in that language.
Testing is what separates a working system from a demo. Before go-live, test with real examples from your own work, such as chats your supervisors have checked, and agree with the team what counts as passing. Test again every time the prompt, the documents or the model change.
The running bill: what you pay every month, and to whom
This bill has five lines, and they are often paid to different parties. On the day you sign, ask whose name each account is in.
Model usage is charged by the amount of text going into and out of the model, counted in units called tokens, and paid to the model provider. It grows with the number of chats, their length, and how many times the agent calls another system.
Hosting covers the servers, the database and the logs, paid to a cloud provider. If you choose a private LLM, the per-call model fees turn into the cost of your own hardware and its upkeep.
Channel fees are easy to miss. Messages the agent sends to customers later, such as appointment reminders, may count against the message quota of the LINE OA plan your company already pays for.
Monthly care is the development team's time after launch: reading real chats to find wrong answers, adjusting prompts, fixing things when a connected system changes, and keeping model spend inside the budget.
Knowledge upkeep is your own staff's time when prices or policies change. Nobody invoices you for it, but if nobody owns it, the agent will give out-of-date answers with full confidence.
Why a chatbot and an AI agent are priced differently
A chatbot answers from knowledge you prepared, and the job ends with the answer. Most of the build goes into the knowledge, the channel and testing the answers. Most of the running cost is model usage per chat.
An AI agent keeps working in your systems after it answers. Every connected system brings its own permissions and approval points, testing has to cover actions as well as answers, and one task calls the model several times, because each time tool calling reaches into a system, the result goes back to the model.
The other reason is the cost of a mistake. When a chatbot is wrong, the customer asks again. When an agent is wrong, you may get a double-booked appointment or an invoice sent to the wrong customer. A chatbot that starts booking slots or opening orders moves onto agent pricing from that day.
Hypothetical case
An air-conditioner cleaning and repair company in Bangkok (name and details invented) takes jobs through LINE OA. Its admins answer the same questions and phone technicians to book visits. In version one, an AI agent answers questions about services and coverage areas from a knowledge base the head admin signed off. The build bill covers one channel, the knowledge base and testing in Thai with real customer questions. The running bill is model usage per chat and a small server.
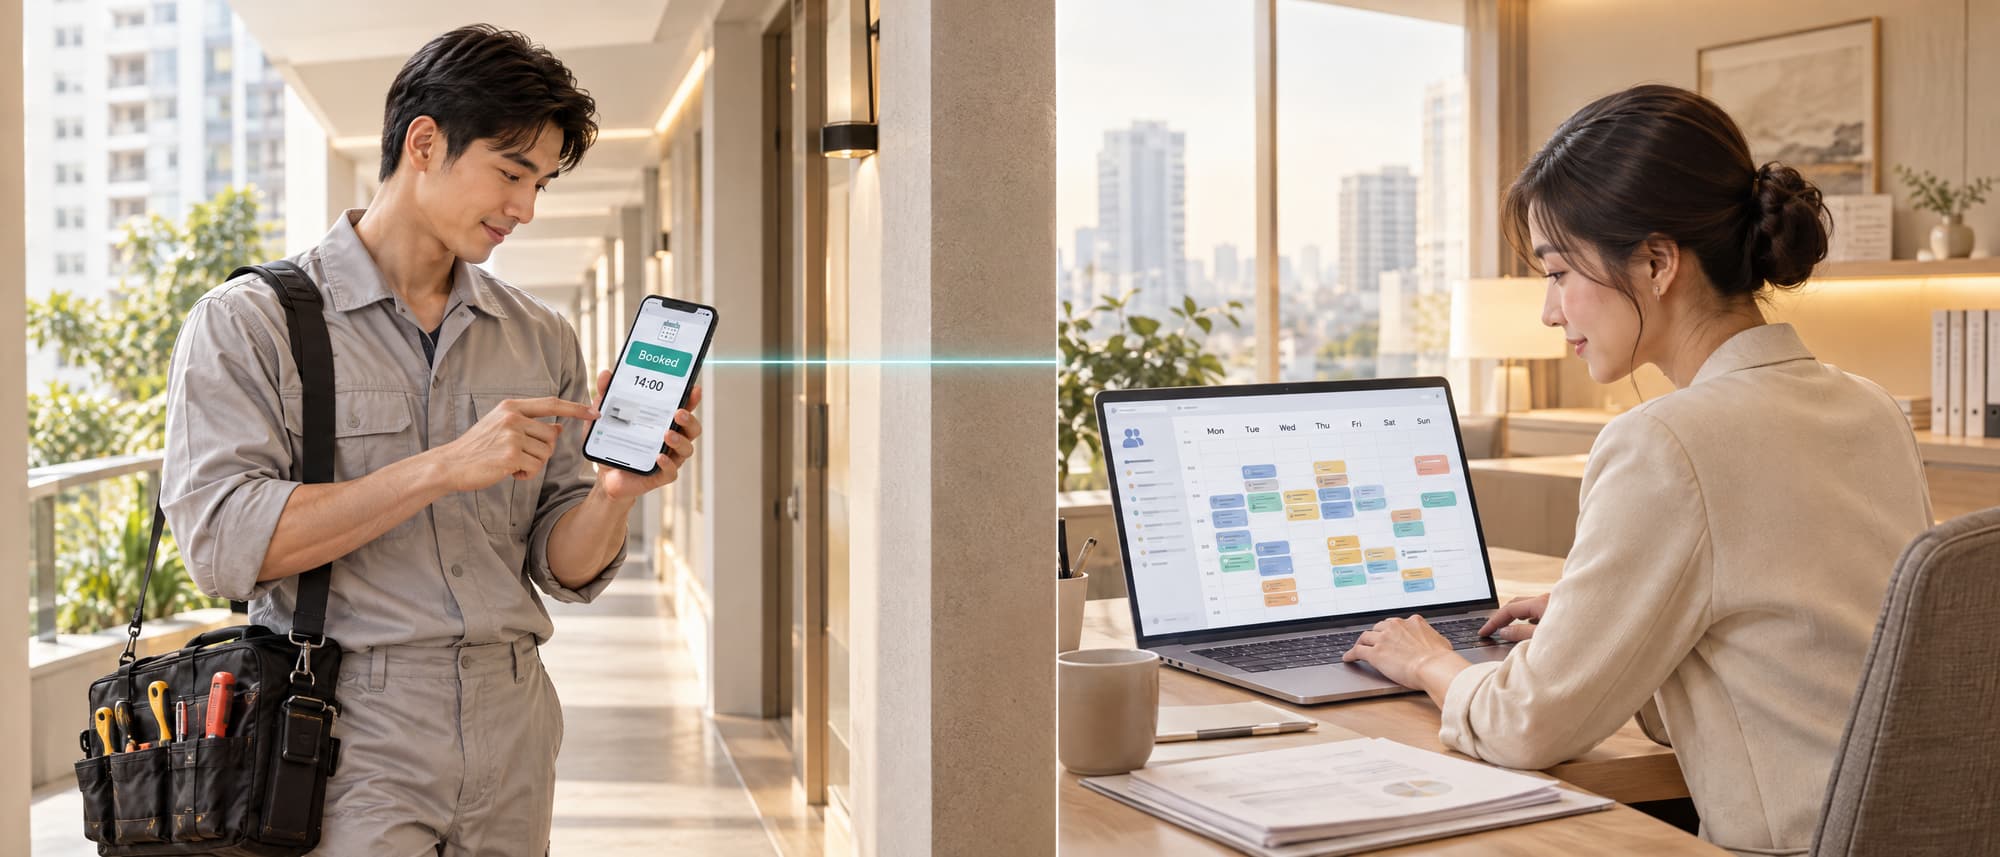
In version two, the agent books technician slots in Google Calendar. The build bill adds the calendar integration, travel-zone rules and a handover to an admin when slots clash. The running bill grows two ways: each chat calls the model more often, and reminder messages count against the LINE OA quota. Version three, as the team proposed it, would issue invoices through the accounting software and answer in Japanese, which adds another integration, an approval step and testing in a second language to the build bill. The owner split it into two phases: invoices first, with an admin approving every one, and Japanese only once booking results held steady.
The three questions that move the price most
The six factors above do not weigh the same. These three questions can be answered in one meeting, and they tell you which way the price will go before you ask for a quote.
Three questions that set the price
- Question 1: How many systems does the agent touch, and does it write or only read? List the systems and mark the ones it must write to. Each one adds work to the first bill and model calls to the second.
- Question 2: What does one wrong answer cost? If the customer simply asks again, light testing is enough. If money goes to the wrong account or customer data leaks, you need approval points, more thorough testing with real cases and possibly a more accurate model.
- Question 3: May the data leave the company? If yes, use a cloud model and pay for what you use. If Thailand's PDPA or your parent company's policy says no, you need a private LLM, which turns per-call fees into hardware and upkeep.
When this does not work: if you cannot answer question 1 because you do not yet know which job the agent should do, choose the job first and ask for a price after.
How small should version one be?
A good first version has one channel, one job, and the fewest systems that let that job finish. Pick work that happens every day and can be corrected if it goes wrong.
Before launch, set a daily cap on model spend with an alert as it gets close, and decide what you will measure, such as the number of chats that finish without a handover. Once the numbers hold steady, add the next system or channel. For the measuring itself, see How to measure AI results without fooling yourself.
| Factor | Build bill | Running bill | How to keep it down |
|---|---|---|---|
| Channels | Integration and testing per channel | Message quota, such as LINE OA | Start with the channel customers use most |
| Knowledge sources | Gathering, sorting, sign-off | Staff time to update | Start with the most-asked questions |
| Connected systems | Integration, permissions, outage handling | Model calls, care | Read-only first, write once results hold |
| Approval points | Case screen, audit log | Approvers' time | Require approval only for money and personal data |
| Language | Testing in each language | Longer chats or a larger model | Thai first, other languages as a later phase |
| Testing | Testing with real chats before go-live | Testing again after every change | Test deeply only where mistakes are costly |
| Where data lives | Private LLM setup | Hardware in place of per-call fees | Run in-house only the work that handles sensitive data |
What a good quote shows
A quote with one total line gives you no way to compare two developers and no idea what you will pay in month three. What to prepare on your side is in What to prepare before you hire an AI developer.
- The channels, the jobs the agent does, and what is excluded
- The connected systems, each marked read-only or write
- What the agent does alone, what it only proposes, and where a person approves
- How it will be tested with real examples before acceptance, and what counts as passing
- Each monthly running cost on its own line, who it is paid to, and whose name the account is in
- How model usage was estimated, the cap, and who is alerted as it nears
- What monthly care covers, and who updates the knowledge base
- What is handed over, such as source code and the knowledge base
- Whether out-of-scope work is priced before it starts
For the development team · Where model usage accrues
Every model call resends the whole context: the system prompt, documents retrieved through RAG, chat history and tool definitions. Spend therefore tracks context size more than question length. The usual spikes come from tool-call loops, retries, test runs and re-embedding when documents change. Controls: model routing that sends classification to a small model, summarizing older chat history, prompt caching, a cap on tool-call rounds per task, token logging per conversation and a daily budget alert. Many tokenizers split Thai into more tokens than English text of the same length, so estimate from real customer chats.
How we price an AI agent so you see both bills
DNA Maker starts by talking to the staff who do the job every day, then writes a scope that names the channels, the connected systems and the approval points, with each monthly running cost on its own line: who it is paid to and whose name the account is in. You see both bills before you decide. Everyone working on it is on our own team.
Scope and price are fixed before work starts. For a first estimate, ask Dream on our chat page. Dream is our own AI agent and gives an estimate within minutes. The first version we propose usually has one channel and one job, with a monthly care plan. When data cannot leave the company, we deploy a private LLM inside your systems. See AI Agent & Chatbot and LINE OA chatbot with AI, or ask Dream.
SOFTWARE ENGINEERING GLOSSARY
Software engineering glossary
| Term | What it is | A simple example | What executives should ask the development team |
|---|---|---|---|
| TCO | Total cost of ownership over the system's life, build and running costs together | The build plus model fees and care over the contract | Does the figure include the second bill? |
| Token | The small unit of text a model counts to charge for usage | A long chat raises the tokens per call | How many tokens does one conversation use, measured on real chats? |
| Tool calling | The mechanism that lets an agent ask to use another system | The agent checks the technicians' calendar before offering a time | How many calls does one task make, and is there a cap? |
| Private LLM | A language model running on hardware your company controls | A staff assistant running in the company server room | How do hardware costs compare with a cloud model? |